

How to write comparison content that doesn't age like milk

Contents
Every marketing lead I talk with sees potential of comparison content, but also see it as a double-edged sword they're not comfortable investing in.
The hesitation usually comes from some mix of (1) it feels unnatural to give your competitors their flowers on your own website, and (2) comparison pages come with maintenance overhead nobody wants to deal with.
Competitors ship things, change their pricing, get acquired (or acquire others), and all of a sudden the article you wrote in March is outdated in June.
So how do you walk the line between being fair (complimentary, even) to your competitors while still capturing demand & showing off your product's strengths? And how do you keep the content accurate once it's out in the world to avoid spreading misinformation?
Both are worth figuring out if you want to write comparison content that doesn't get dunked on. And both are things I'm here to give some answers to based on our experience writing comparison content at PostHog.
Why bother with comparison content?
Because it works.
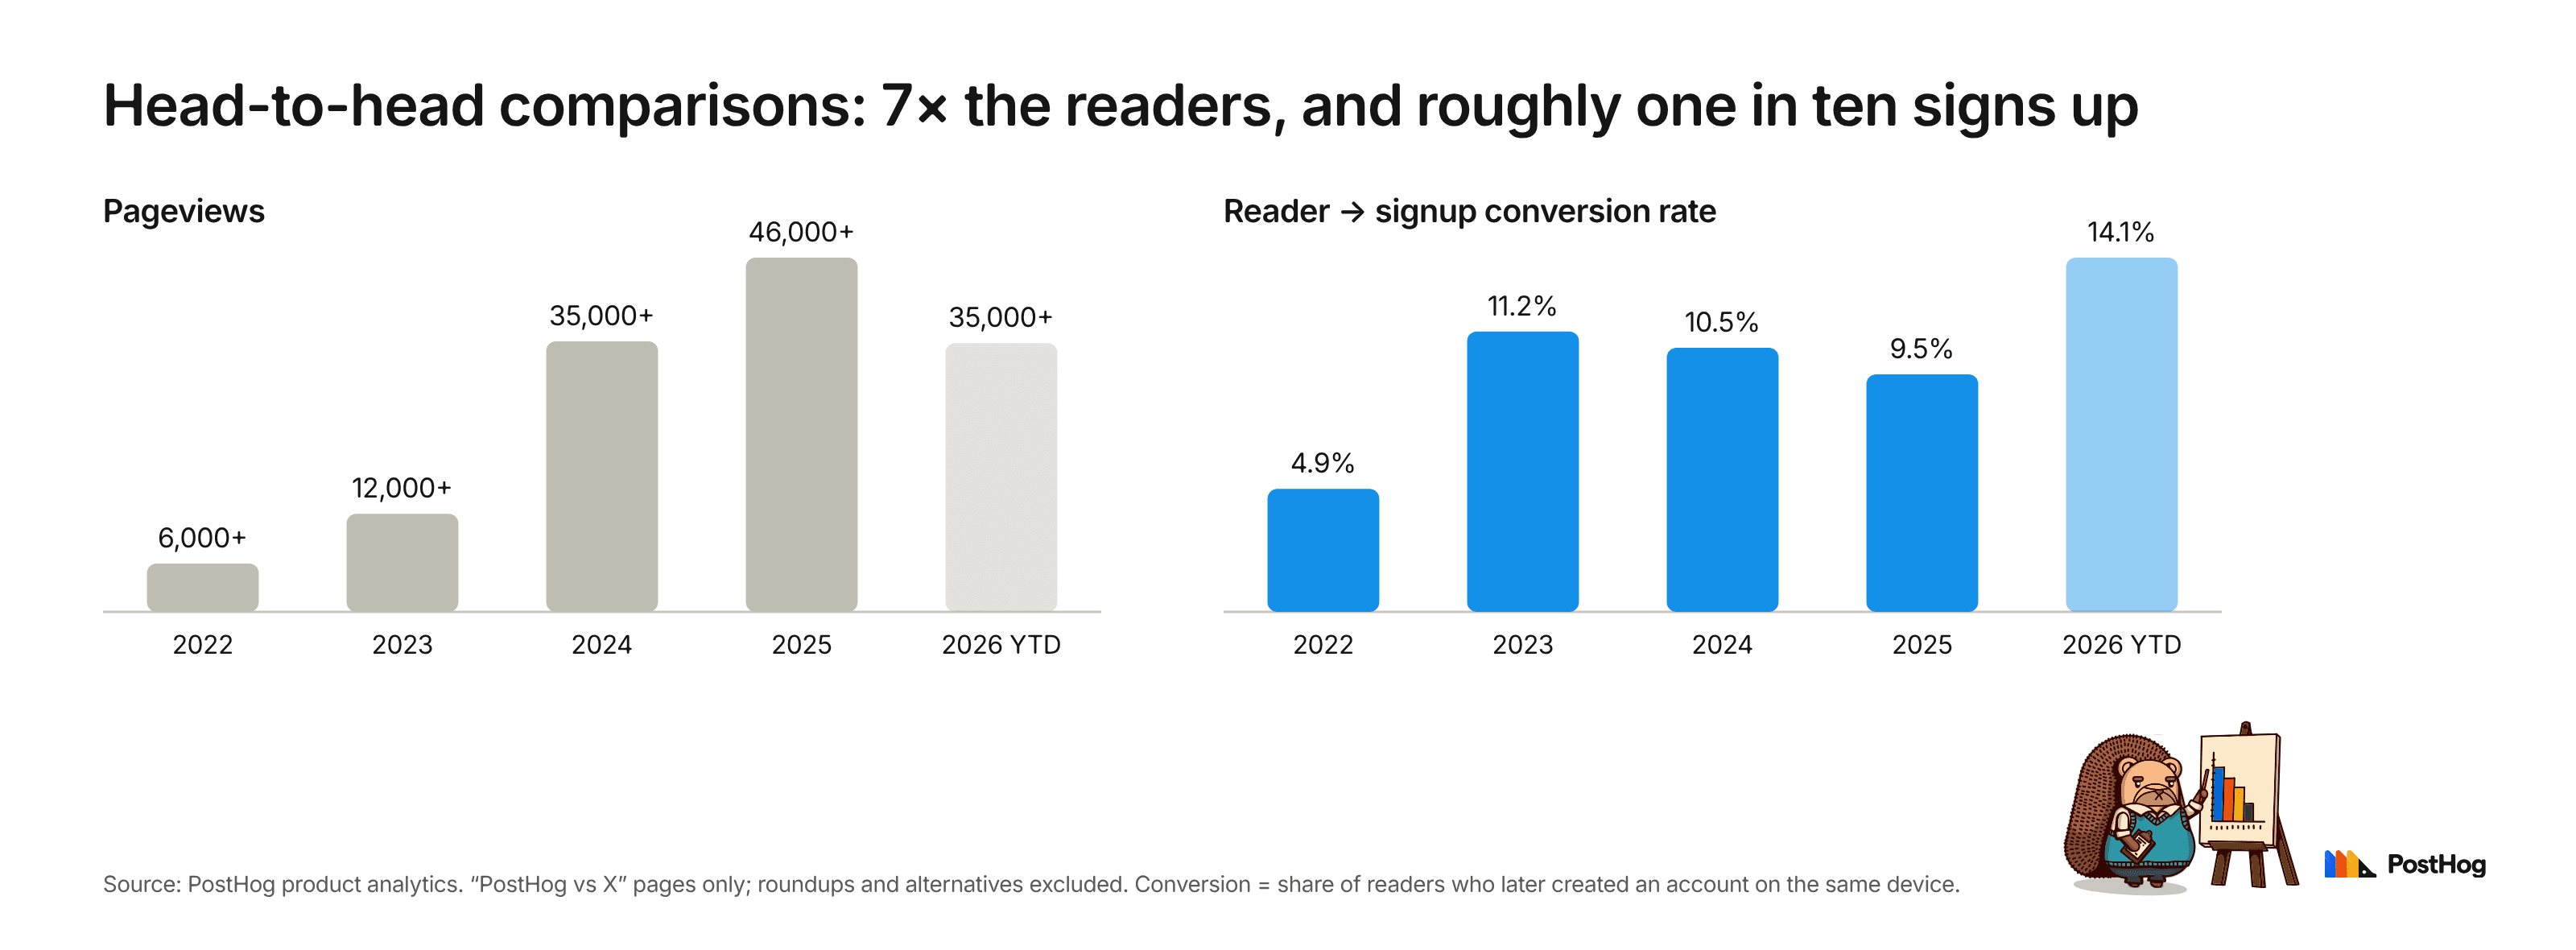
Since 2021, over 25k people have signed up for PostHog after reading a comparison. Almost 50% did it within 24 hours of reading; ~75% within 30 days.
| Content type (2025 FY) | Unique visitors | Visitors who later signed up | Conversion |
|---|---|---|---|
| Head-to-head comparisons (PostHog vs X) | 30k+ | 3,000+ | ~10% |
| Alternatives and "best X tools" roundups | 100k+ | 4,000+ | ~4% |
| Every other blog post | 250k+ | 6,000+ | ~2.5% |
It makes sense why they overperform. Someone searching for this style of content has already decided they need something, the only question left is which one. Comparison content sits at the sweet spot in the funnel where that decision gets made, and your job is to help make it (ideally in your favour, but not always and that's okay. More on that later).
Our credentials
Technically, our first comparison was a roundup. The best open source analytics tools went live in October 2021 and is still our single most-read piece of comparison content, at 150k+ pageviews and counting.
It set the template for the early days: "best open source X" for session replay, A/B testing, and feature flags. Open source was one of our wedges, so that's what we compared on.
The first head-to-head, PostHog vs Amplitude, followed in May 2022. It still gets a few hundred readers a month, which is more than I can say for most things we published back in 2022. Matomo and Mixpanel came next.
2023 was the year it became a thing. Every new PostHog product came with a new set of competitors. Session Replay brought Hotjar, FullStory, and LogRocket. Feature Flags brought LaunchDarkly, GrowthBook, and Statsig. Web Analytics brought GA4.
We went from three to fourteen in a year, and the maintenance problem flared up. Three pages you can keep accurate by hand; fourteen, each with a feature table and pricing that changes every quarter, not so much. It's, to this day, a workflow we're constantly working on solving for and improving.
2024 was the alternatives year. A lot of our competitors got a "best X alternatives" piece: Hotjar, Statsig, Plausible, Matomo, and about fifteen more. We also launched error tracking, wrote PostHog vs Sentry in August, and watched it become our most-read head-to-head of all time within two years.
2025 and 2026 followed the products; Best Sentry alternatives and best error tracking tools for error tracking, best open source LLM observability tools for AI observability, and best Datadog alternatives as the first hint of what was coming next. Most recently we started doubling down on our observability stack: PostHog vs Langfuse and a full set of AI observability roundups (best AI observability tools, plus Langfuse, LangSmith, and Braintrust alternatives). Then logs: best log monitoring tools, Grafana Loki and Splunk alternatives, and PostHog vs Datadog.
This isn't an AEO fad for us; we were writing comparison content BeFoRe iT wAs cOoL, back when the answer engine was a guy named Greg on Stack Overflow.
And while they have shapeshifted plenty since then, we've stayed true to two principles:
- Do no harm. We don't trash-talk competitors, we don't straw-man them, and we admit when and where they're better than us. No sneaky shit, as our handbook puts it.
- Respect the reader's intelligence, and meet them where they are. A developer comparing tools is smart, busy, and already halfway towards a decision. Give them the answer as accurately and as directly as possible, and let them make the right call for their product and use case. Also, they can tell if you're generating AI slop comparisons, it's a bad look.
Be the comparison page you'd want to read
PostHog doesn't have every feature every competitor has (yet), and we're fine admitting it. Our credibility with the reader is worth more than whatever we'd "win" by fudging the truth.
We're not the solution for everyone. We are the best solution for someone (a lot of someones, actually), and the job is capturing their attention. Which means you will, occasionally, lose a deal on your own website: someone reads PostHog vs Competitor, concludes Competitor is the better fit, and goes and buys Competitor. We wish them godspeed and focus on our ICP anyway.
In practice, this means picking up a few uncomfortable habits:
Acknowledge your gaps and credit their wins.
"If you need X, they do it better than we do today" is a sentence you'll find on our pages. Softening it with what's coming is fine (a roadmap link, a "we're working on it"), as long as you're clear about where you are right now for the readers deciding today.
For example, earlier this year our articles admitted we were weaker on APM because we hadn't shipped distributed tracing or metrics yet. True at the time. We've since shipped a full APM suite, and the articles now say that instead. Our content matches our shipping, not just our ambitions.
Readers don't think less of you for crediting a competitor; they think more. It's the cheapest trust signal in content marketing, and almost nobody uses it. And as AI eats everything else about content, trust is one of the few things left you can't generate. Say the nice thing.
There's another reader to keep in mind, too: LLMs. When someone asks Claude "PostHog vs Sentry for a Next.js app," we assume the model pulls from sources it judges to be balanced. So be balanced. You want to read as a source, not an ad.
Being honest used to be a brand decision (one we've proudly stood behind), but now it might be a distribution decision too.
Write a "who should pick them" section.
If you can't write a fair paragraph about where your competitor wins and who they might work better for, you don't understand them well enough to compare. Go read their docs.
It's also the place to be honest about who you are and aren't building for: plenty of our competitors are openly built for marketers for example, and while lots of marketers run all their reporting on PostHog (yours truly included), we're still building for AI-pilled engineers first, and we say so.
The reader who isn't a fit should leave feeling helped, not hustled. Honest pages also don't make enemies: the fastest way to go viral for the wrong reasons is a dodgy comparison, and if you'd rather not be bashed on Hacker News or Twitter for being slimy, be fair.
Take corrections from competitors.
We've shipped edits because someone at a competitor emailed us, DMed us, or better yet, opened a PR directly against our blog. We welcome it and encourage it. (Yes, if you're a competitor reading this, this is an invitation.)
Here's an example from today:
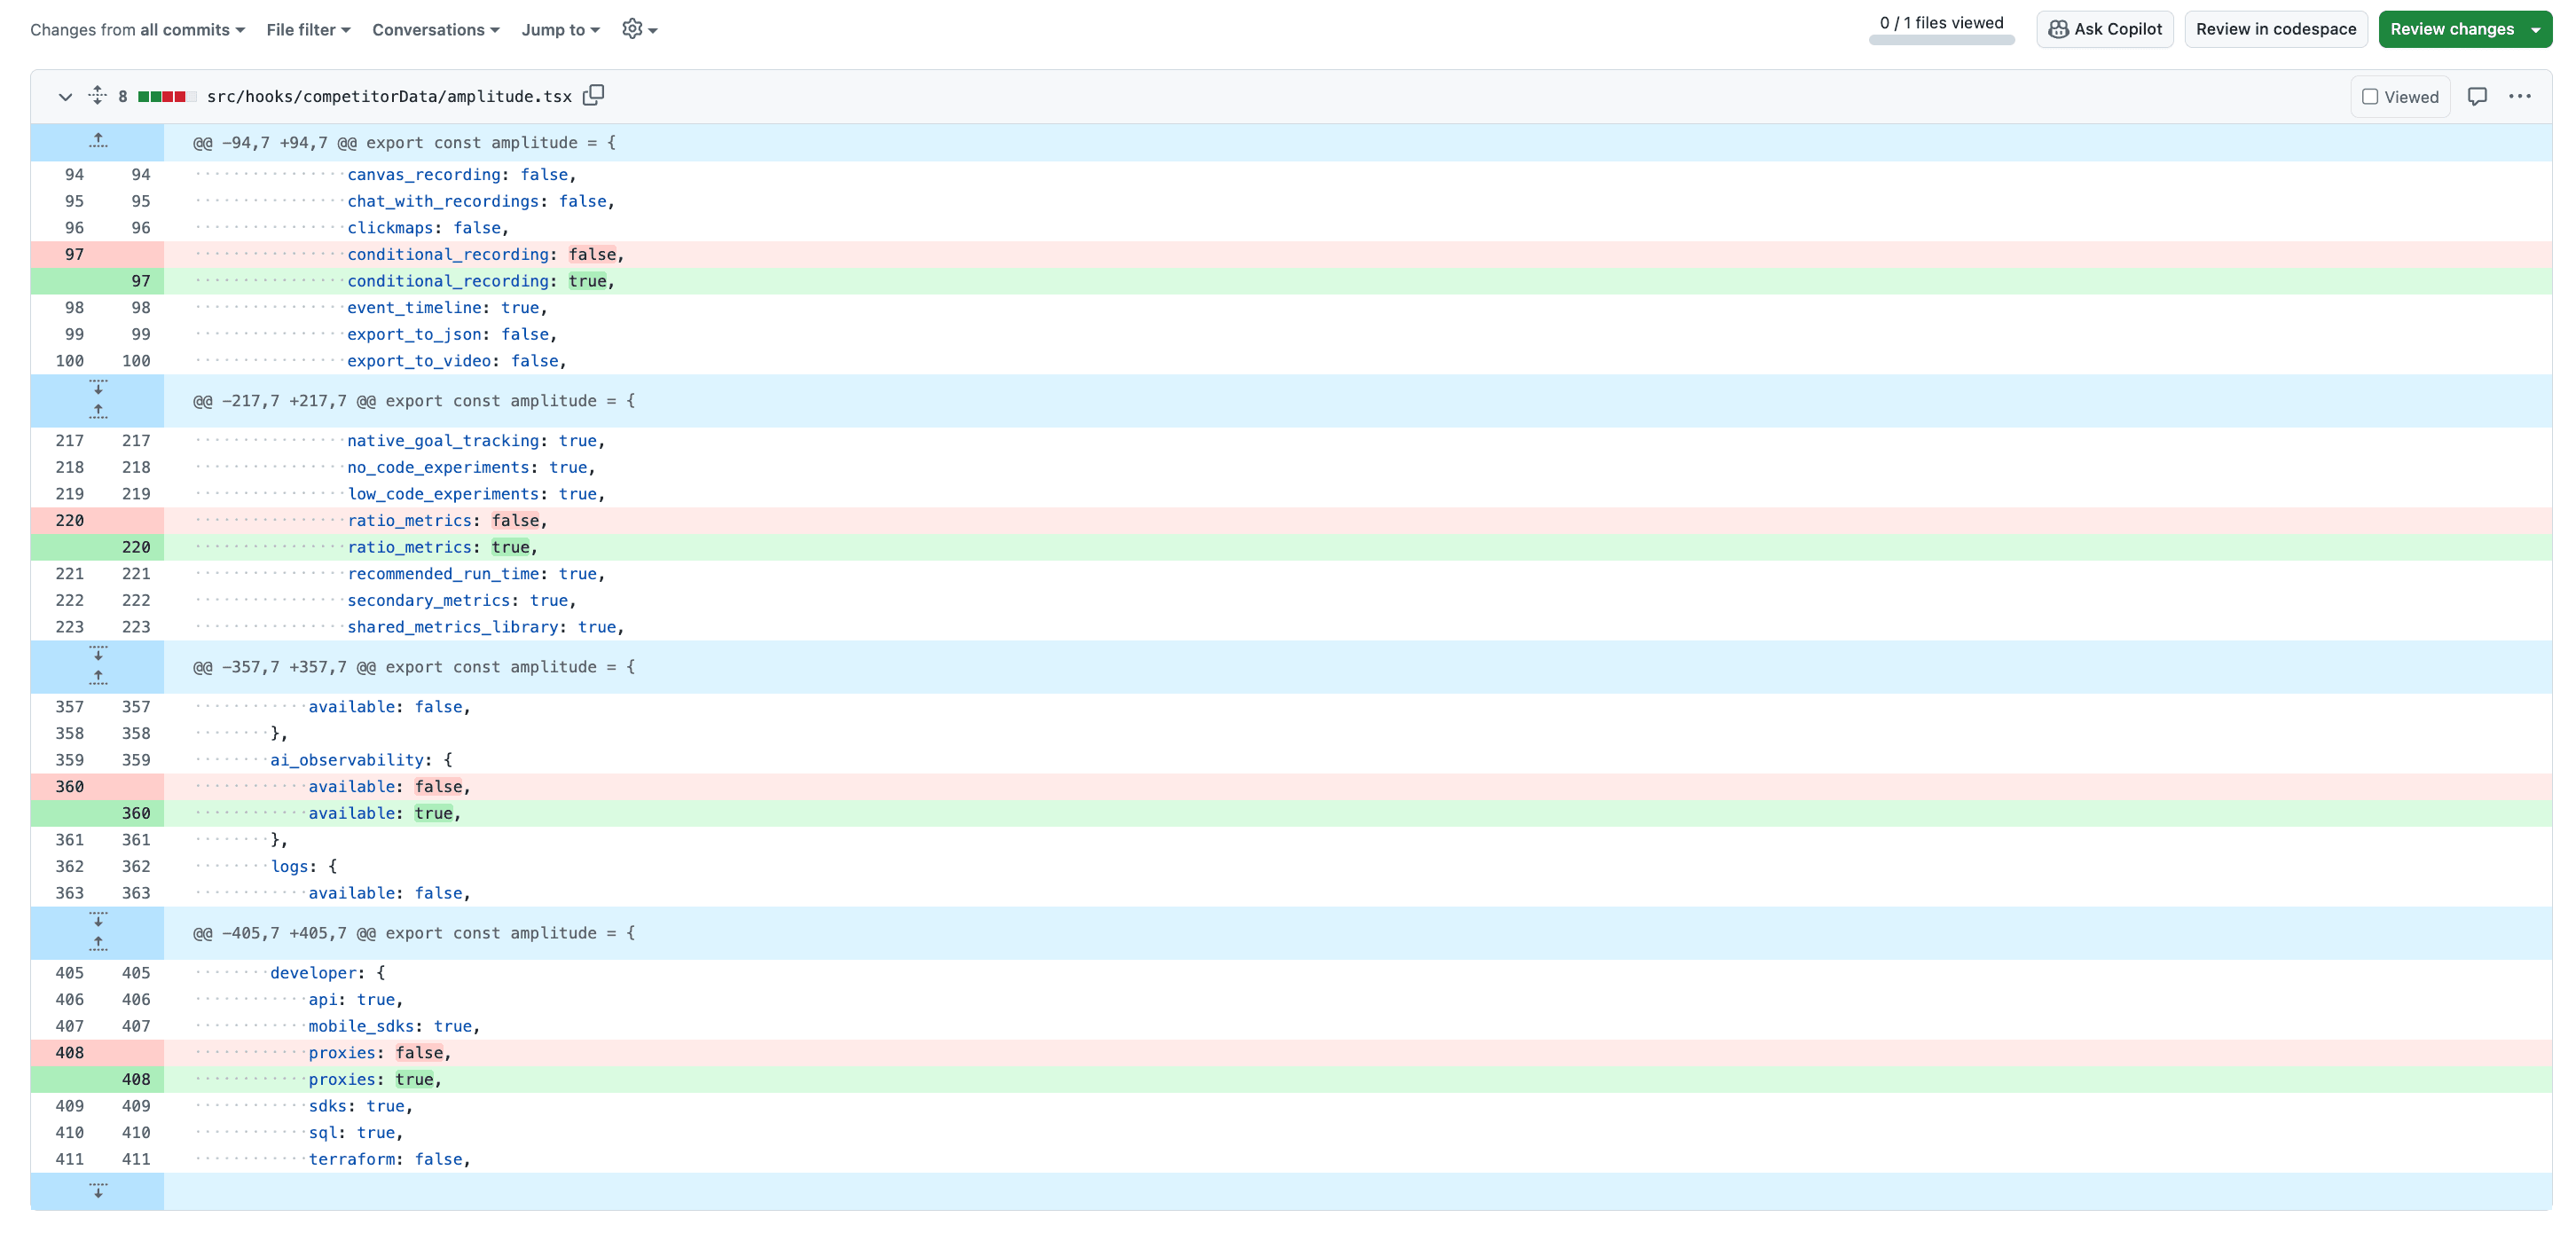
Lucas Harras, a Senior Customer Success Architect at Amplitude, read our PostHog vs Amplitude page, found four features we'd marked as missing that Amplitude actually has, and opened a PR.
We merged it the same day, and because every comparison table renders from that file (more on that below), every page that mentions any of these features was corrected by the next deploy.
Sometimes you'll be offered a slice of humble pie, and it's important to eat it gracefully.
My litmus test for every comparison: if a competitor wrote this exact page about PostHog, how would I feel reading it? Would it feel like they'd done their homework, or would I feel misrepresented and annoyed? If it's the latter, it's probably worth trying again.
We haven't always gotten this right. Part of it is that not everyone uses the same words for the same features, and some of our competitors have several hundred of them. A "sort of" column doesn't exist, so every row is ultimately a judgment call, and we've made some wrong ones.
But we're committed to doing better every time.
How to maintain comparison pages
Staying accurate across ~90 comparison and roundup pages for years is an engineering problem, and we started treating it like one.
1. Every competitor is a centralized data file.
In the posthog.com repo there's a folder with one file per competitor: sentry.tsx, amplitude.tsx, hotjar.tsx, and so on. Each file holds everything we claim about that company, in one place; here's a simplified version of what that looks like:
Feature keys come from a shared dictionary, so "session replay with network payloads" means the same thing on the Hotjar page as the LogRocket page.
Most of our comparison tables render from these files through one component. When a competitor ships a feature, someone changes one line in one file and every page that mentions them updates on the next deploy. The repo is public, so competitors can see exactly what we say about them and open a pull request if we're wrong.
2. Scouts checks our homework
Data files solve "update once, publish everywhere", but they don't solve for "notice that something changed" – that's what we've used Scouts for.
We run two. The first watches our competitors: it reads the competitor files I mentioned above, visits each competitor's pricing and docs pages, and reports back when what they say and what we say have drifted apart.
The second watches us. It turns out a very embarrassing way to get a comparison wrong isn't overstating a competitor, but understating yourself. (I learned this the hard way… occupational hazard of shipping as fast as we do. *wink*)
So the second scout reads our comparison pages against our own changelog, docs, open PRs, and Slack threads, and flags anywhere we might be underselling ourselves.
A few things make both of them better than a script that pings you every time a page changes:
- It has memory between runs, so it doesn't re-flag the same thing every week, and it learns what "normal" looks like for each site.
- It's selective by design. Most runs end with nothing to report, and that's it working. It ignores changes that don't affect the overall comparison.
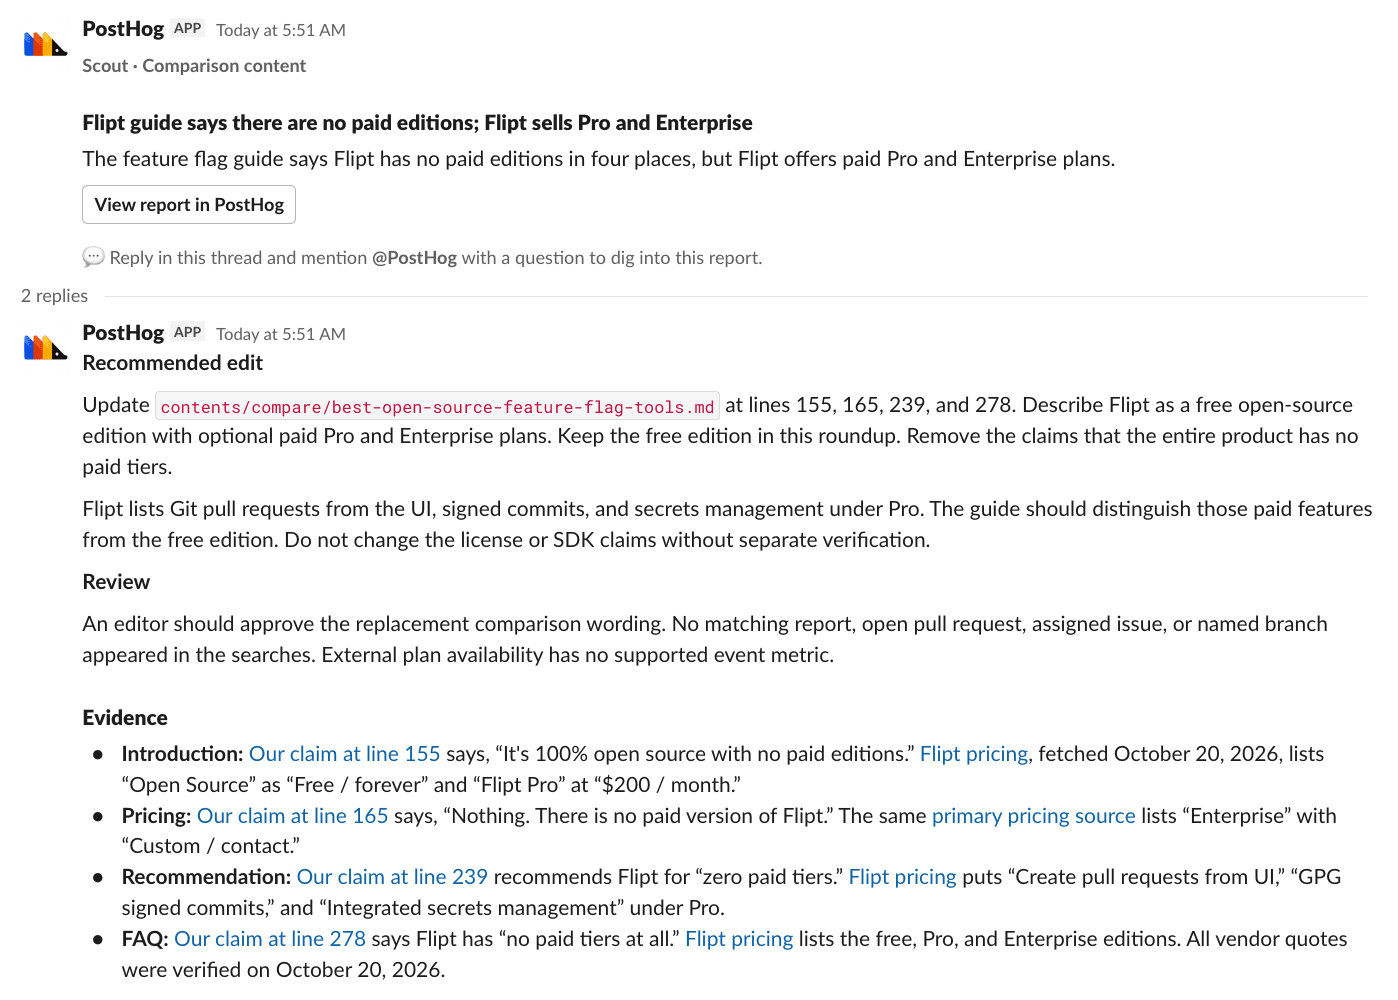
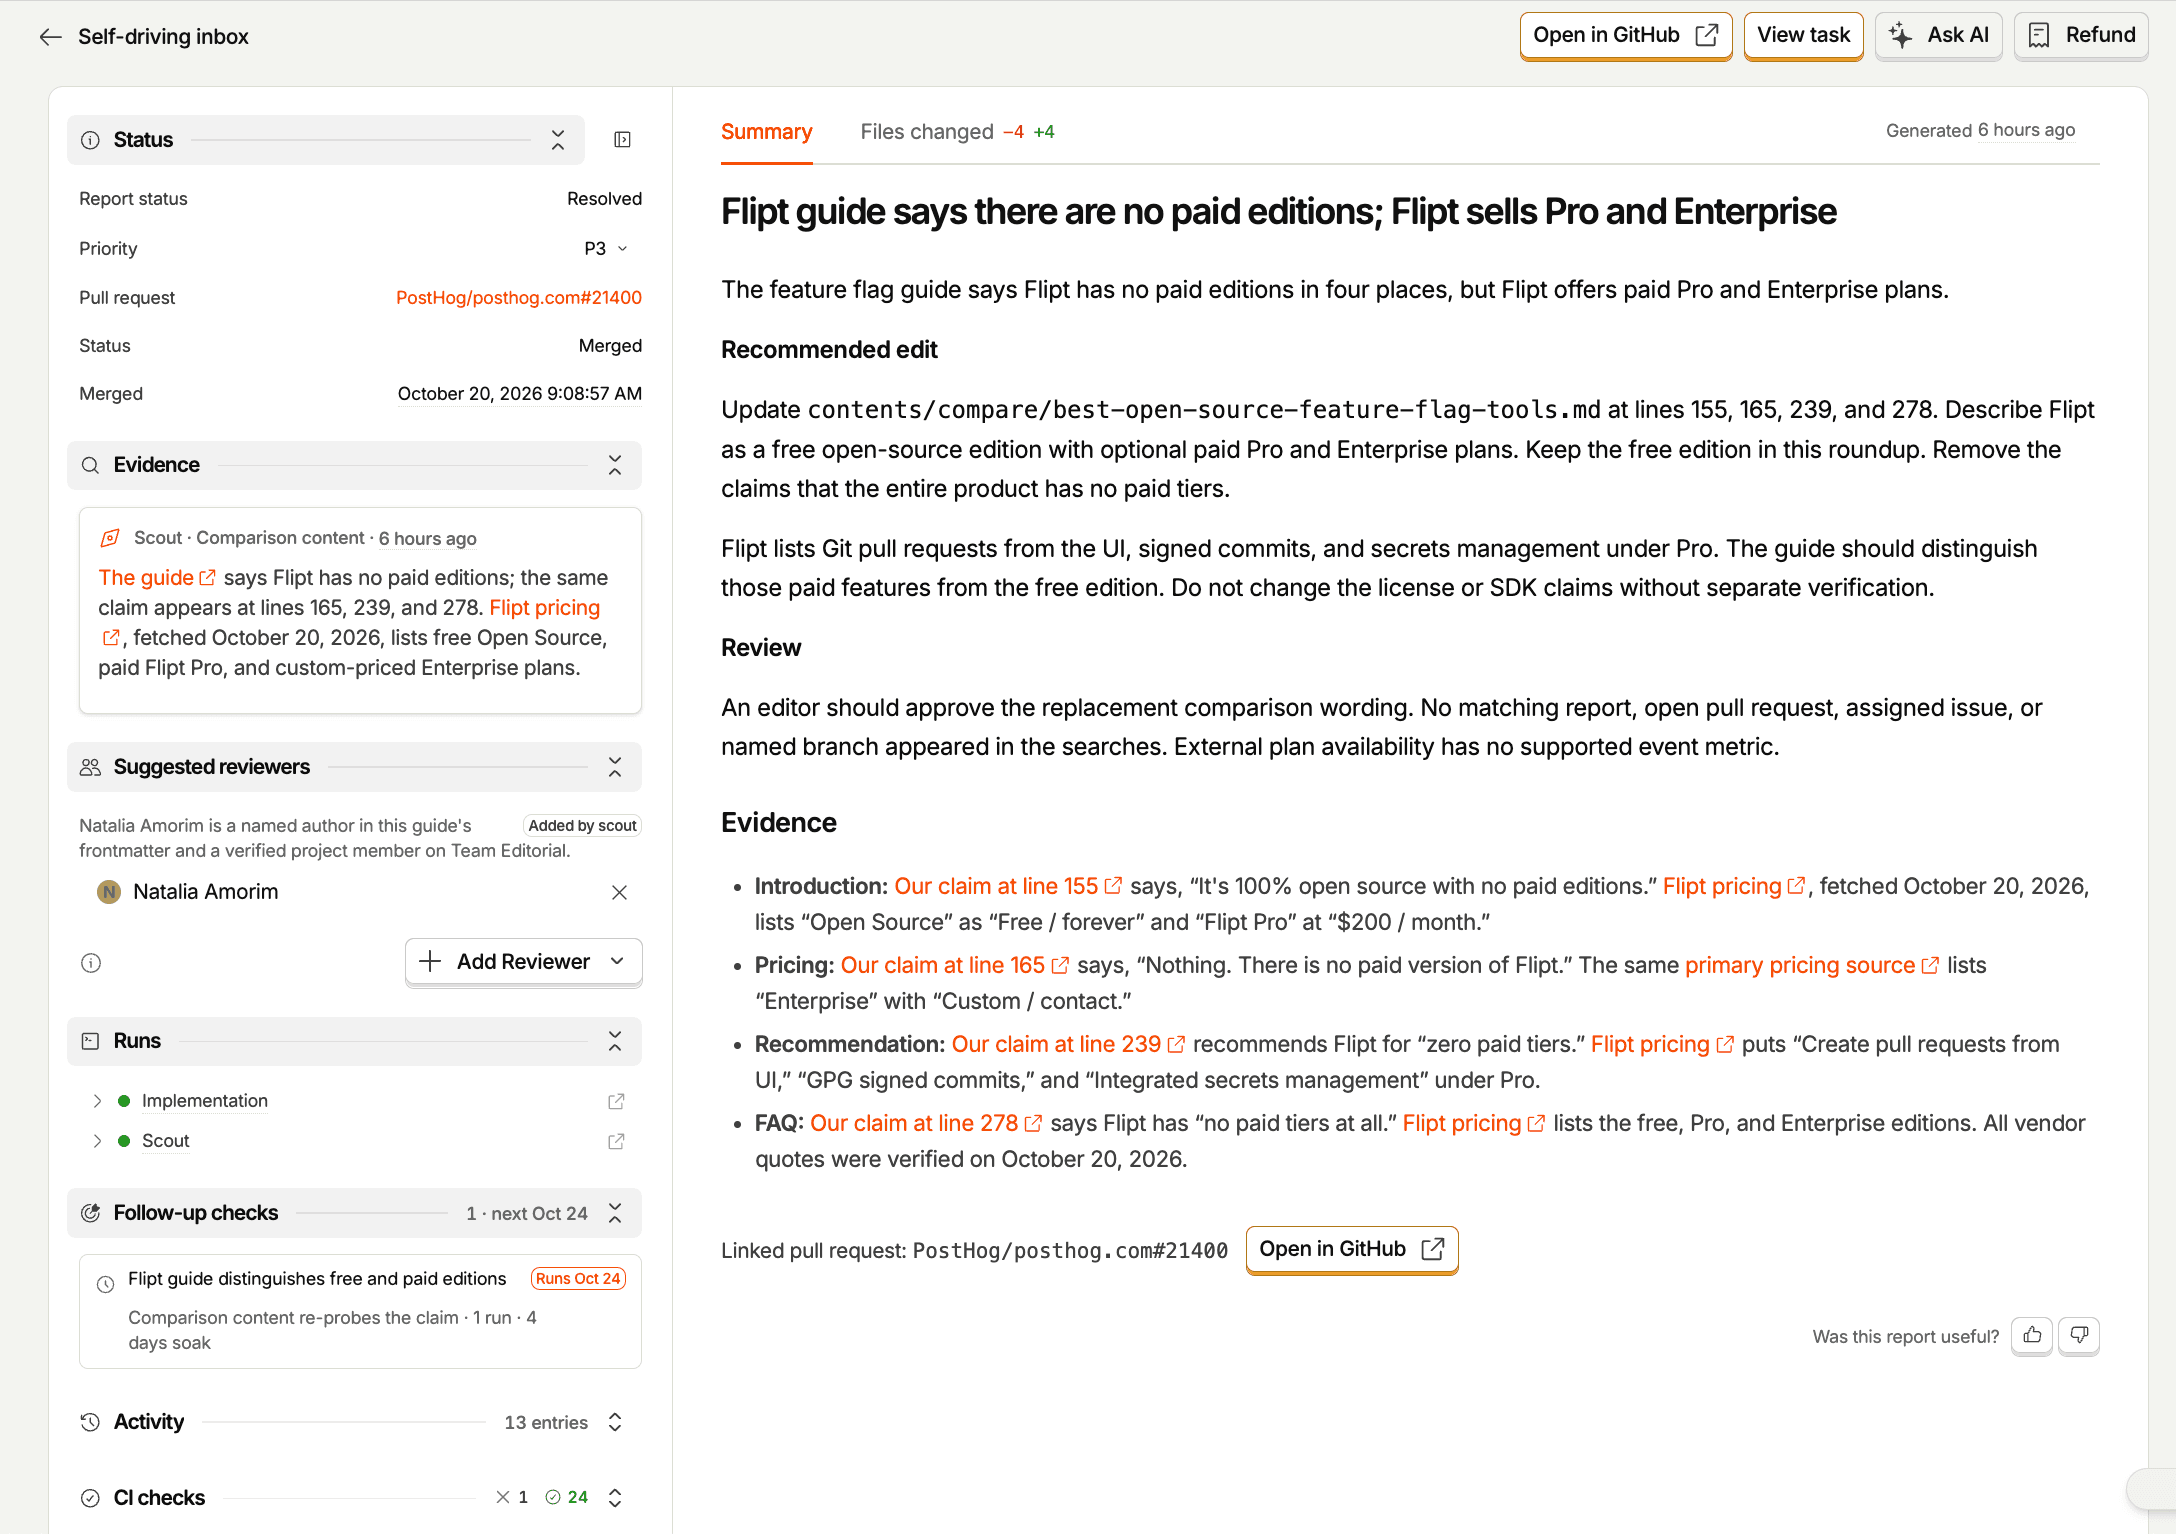
- It shows its evidence: what their page says now, what our file says, and a suggested edit, with sources.
- A human ships the fix. The scout posts a digest to Slack with a link to open a PR. A person decides whether the change is necessary, opens the PR, and merges it.
Here's an example of what this looks like in practice. First, the Slack digest:
Then the full report in our self-driving inbox:
And finally, a pull request ready to merge:
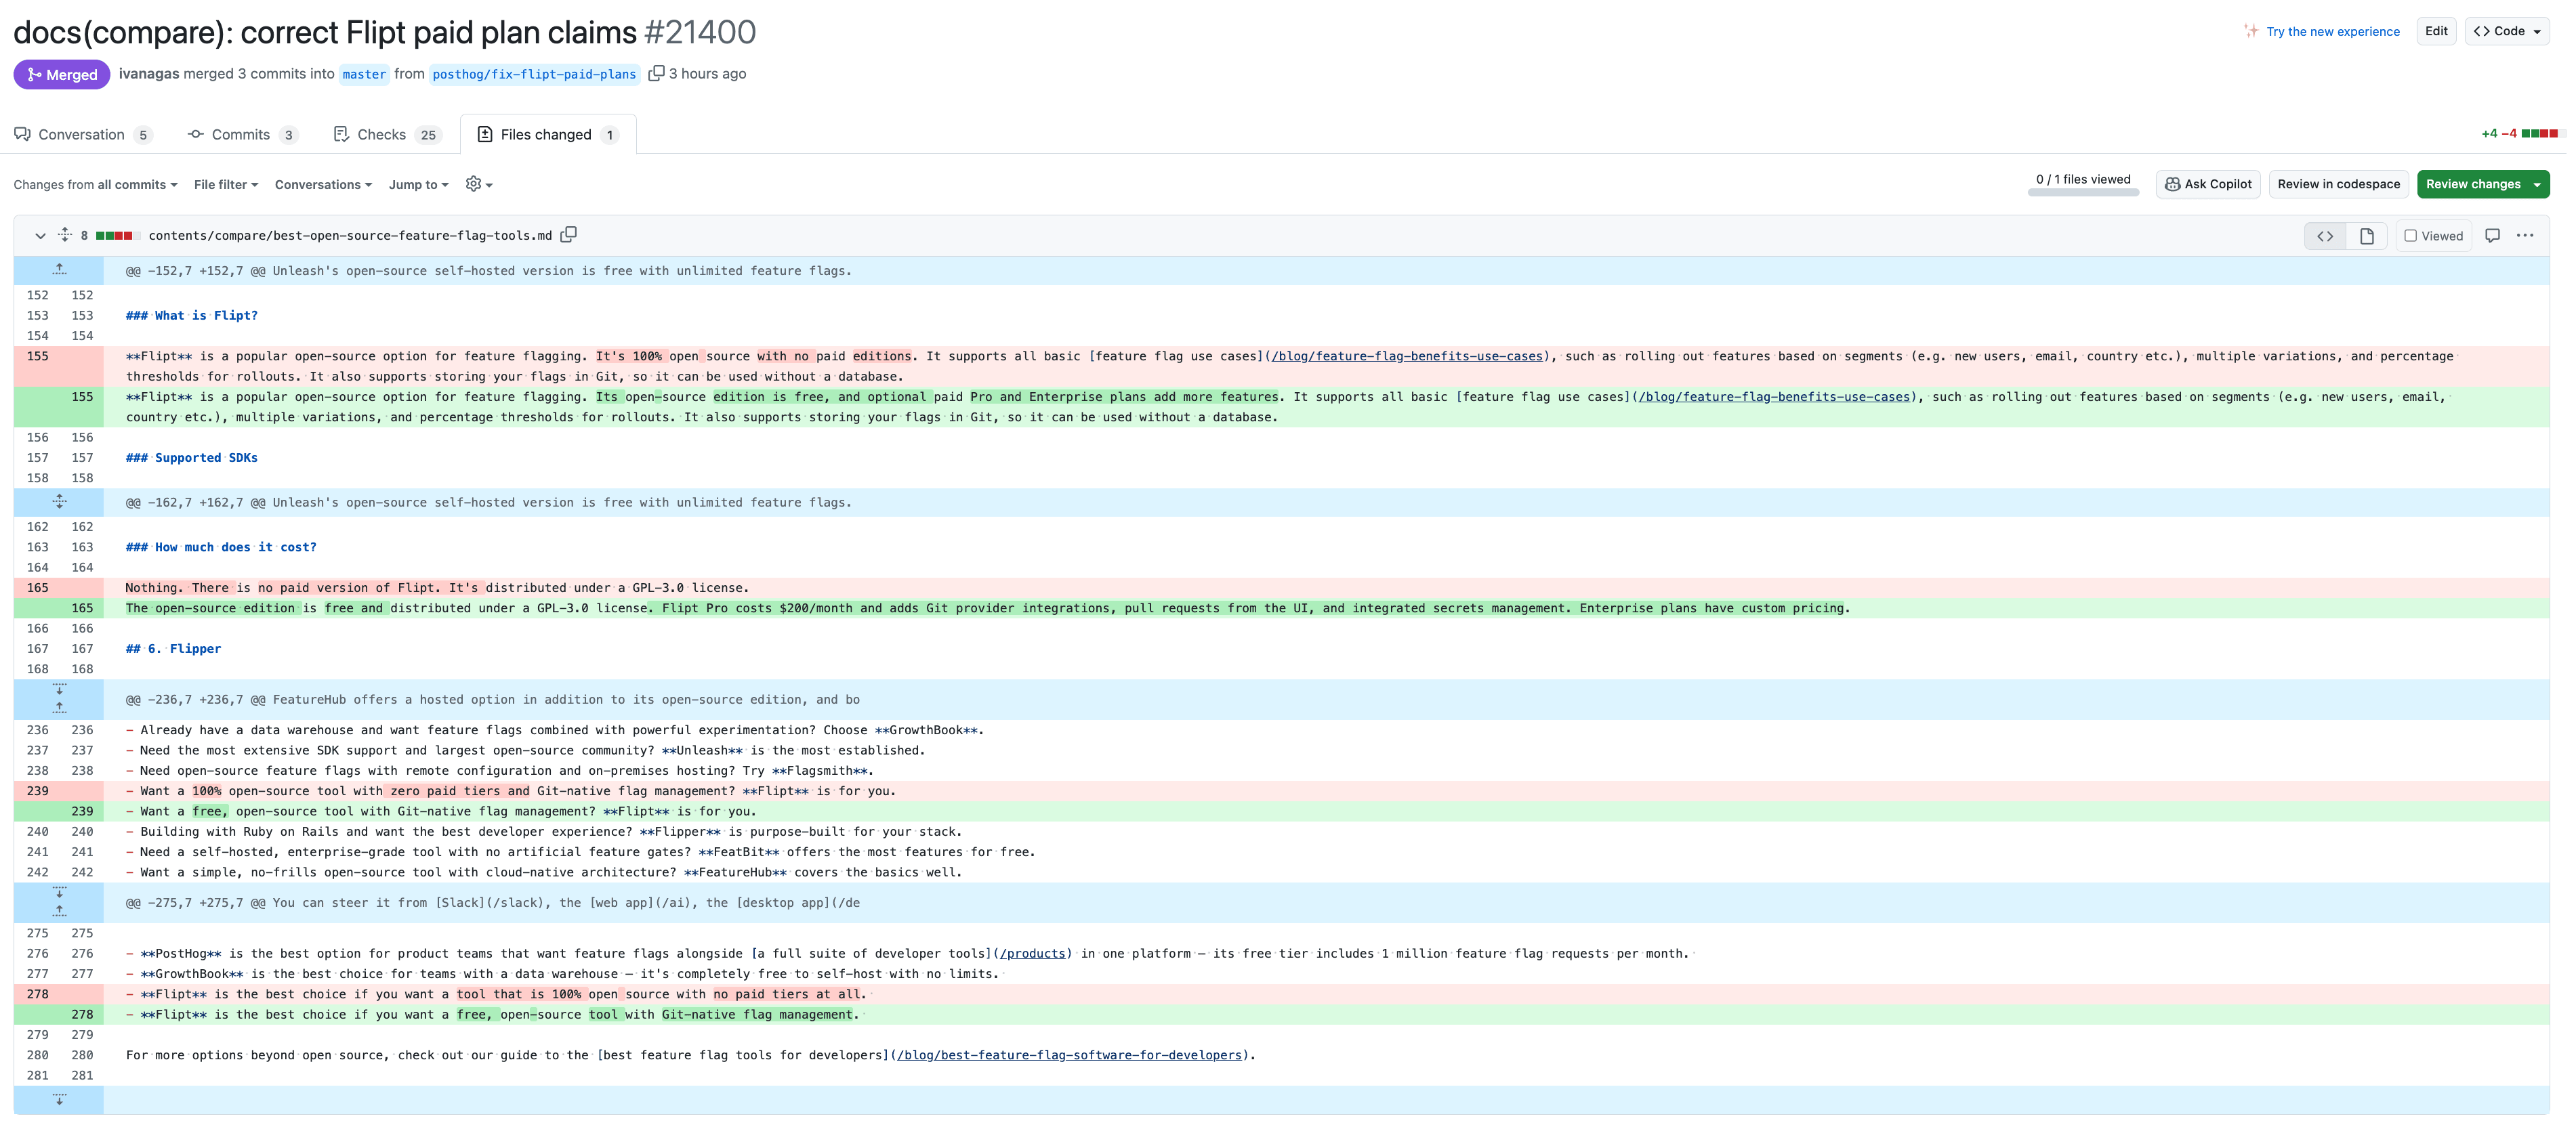
The scout does the noticing, a human does the deciding, and nobody needs to add a recurring "re-read every competitor's pricing page" task to their calendar. Amen to that.
Where we go from here
We haven't reached our final form yet (will we ever?). One of my goals this quarter is going back through all of this content and making it better, and I'm sure there's plenty we're still getting wrong.
But the point is we started. Five years, 90-ish pages, and tens of thousands of signups later, "write honestly about the people trying to eat our lunch" has turned out to be one of the best decisions we've made for our organic content strategy; not the most intuitive one, but still one of the best.
So if you've been circling the plunge, take it. Be fair, be accurate, and let a robot handle the maintenance so you don't have to. (May I suggest ours?)
And if you're a peer who's nailed this (or who has failed at it and has war stories and words of caution to share), my DMs are always open.
PostHog is your product's context layer. With a full suite of developer tools – AI observability, product analytics, session replay, feature flags, experiments, error tracking, logs, and more – PostHog ingests and stores all the data agents need to diagnose problems, uncover opportunities, and ship fixes. A data warehouse and CDP tie it all together, unifying that context into one source agents can read across. You can steer it all from Slack, the web app, the desktop (PostHog Desktop), or your own editor via the MCP.